Your Browser No Longer Just Displays the Web: It Starts Acting on Your Behalf
Firefox learns your history while Chrome can already navigate logged-in accounts, fill forms, and prepare purchases. This shift transforms the browser into an execution environment for AI agents and moves the boundaries of security with it.
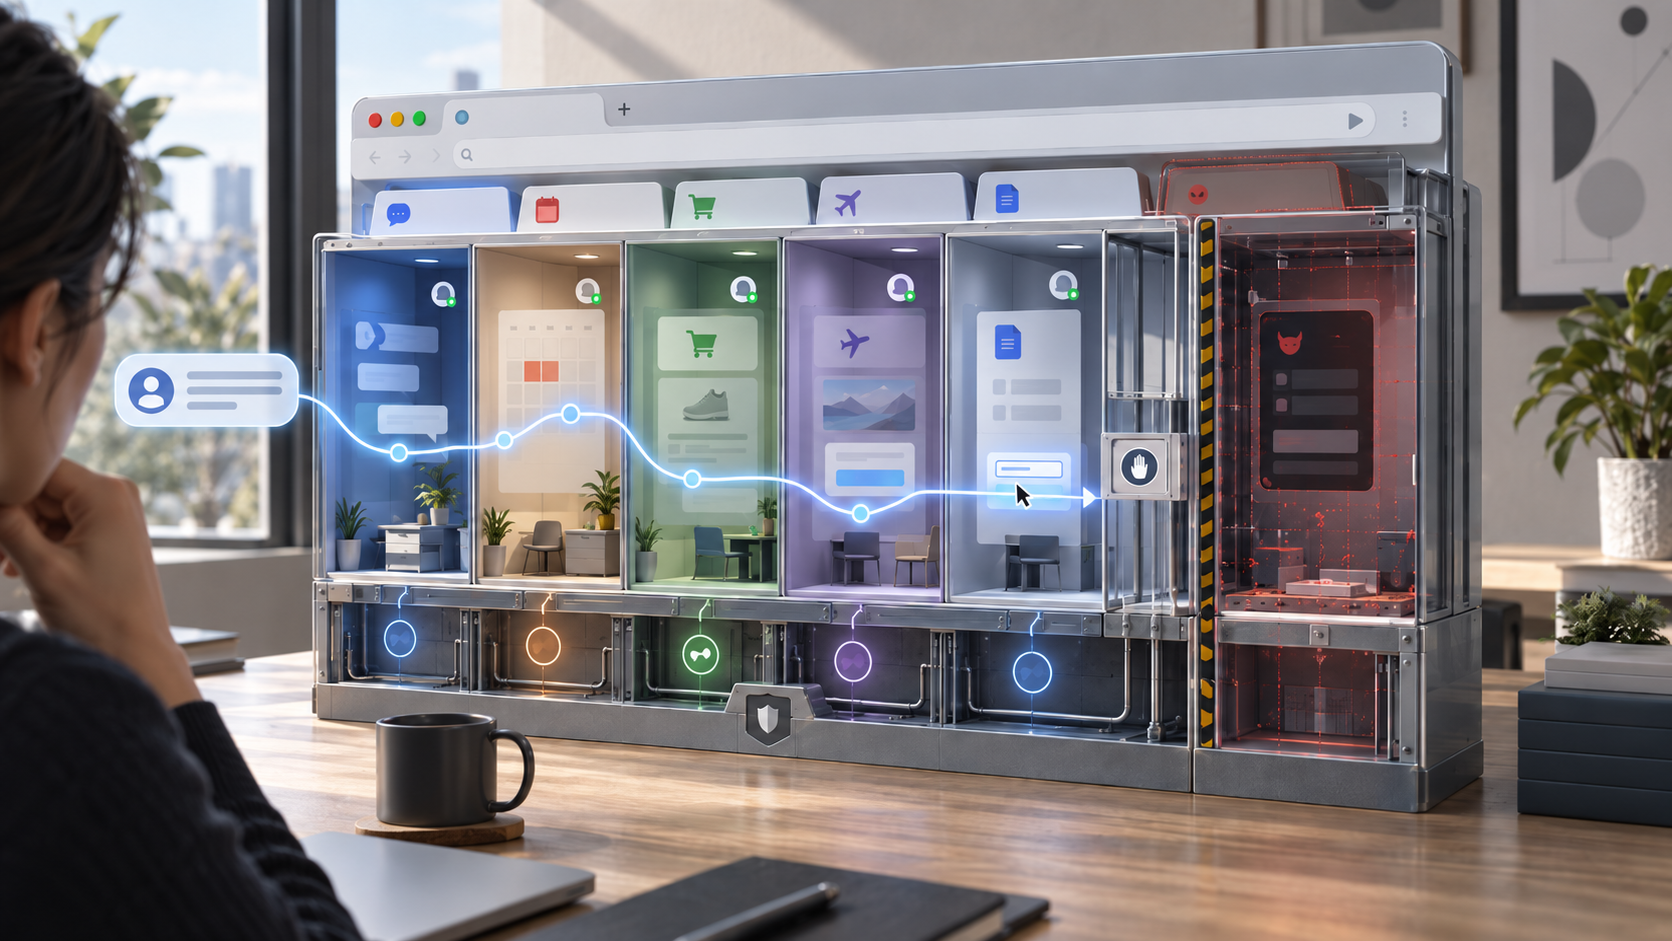
Just a few years ago, delegating a task to your browser mostly meant asking it to auto-fill an address, remember a password, or restore tabs.
In 2026, that definition no longer holds.
Chrome can now entrust multiple steps of a task to Gemini: browse sites, fill forms, use an already authenticated session, add products to a cart, organize a booking, or leverage Google Password Manager with permission. Firefox, for its part, has just introduced Smart Window in France, a window in which an assistant can exploit open pages, retrieve certain history elements, and build a memory of how you browse.
Yet the two browsers do not offer the same thing. Firefox precisely refuses the most agentic capabilities that Chrome is beginning to adopt.
And it is this difference that best reveals the shift underway.
The true revolution of the AI browser is not that a chatbot has been added to a sidebar. It is that the browser already possesses almost everything a software agent needs: context, identity, authenticated sessions, a network, applications, permissions, memory, and an interface allowing it to act.
In other words, the browser is beginning to occupy for AI agents a position strangely close to the one the operating system occupied for classic software.
Not because it replaces Windows, macOS, or Linux.
But because it becomes the environment in which a human intention can be transformed into actions on the digital world.
The Decisive Boundary Is Not Between Firefox and Chrome, But Between Reading and Acting
Smart Window arrived for French users with Firefox 155, published on September 1, 2026. Mozilla describes it as an optional window integrating an assistant capable of summarizing pages, comparing information, working from multiple tabs, and retrieving previously visited pages.
It can also modify a small part of the browser’s state: group tabs or close those matching a request.
But Mozilla then draws a remarkably explicit line.
Smart Window cannot click in your place on a page, fill a form, make a purchase, book a flight, modify browser settings, log in with your saved credentials, or “act independently.” It also has no access to passwords, payment information, unread emails, or local files.
Chrome auto browse crosses that boundary.
Google allows Gemini to build a plan, then actually navigate web pages by clicking, scrolling interfaces, and filling fields. Google cites, among others, bookings, administrative forms, expense reports, subscriptions, tax document retrieval, professional quotes, and purchases.
The current documentation goes even further: the agent can use sites on which the local browser is already logged in and, with permission, ask Google Password Manager to help open a session on certain accounts. Gemini Spark can also exploit the local browser or switch to a remote browser to continue certain tasks.
As of the publication date of this article, auto browse remains limited to the United States on desktop, for eligible Google AI Pro or Ultra users, with a gradual rollout. One must therefore not confuse the technical existence of this architecture with its global availability.
This table summarizes the architectural difference better than a list of functions:
| Capability | Firefox Smart Window | Chrome auto browse |
|---|---|---|
| Understand the current page | Yes | Yes |
| Exploit multiple tabs | Yes | Yes |
| Query history | Yes, depending on requested context | Some Gemini functions can exploit browsing context |
| Memory/personalization | Yes | Yes, depending on enabled features |
| Organize the browser | Tab grouping/closing | Yes within agentic tasks |
| Click in a site | No | Yes |
| Fill a form | No | Yes |
| Use an already connected session | Not to act in the account | Yes |
| Exploit a password manager | No | Yes, with permission and without directly revealing the password to the model |
| Perform a multi-site task | Essentially analysis and planning | Yes |
| Automatically finalize any sensitive action | Not applicable | No: certain steps require confirmation or handover |
Firefox is therefore today building mainly a context-aware browser.
Google is already experimenting with a browser capable of exercising its user’s authority.
This is a much deeper difference than it appears.
The Password Is No Longer the Real Privilege
When discussing AI access to our accounts, the instinctive question is: “Can it see my password?”
In Chrome, Google says no. When auto browse uses Google Password Manager, the manager handles authentication without transmitting the raw secret to Gemini.
That matters.
But it almost masks the most interesting problem.
Suppose you are already logged into Gmail, Amazon, your insurance, your phone carrier, or an administrative portal.
The browser then generally retains cookies, session tokens, and other authentication states that tell the service: this user has already proven their identity.
Software capable of acting inside that session no longer necessarily needs the password.
To understand the stakes, one must distinguish the secret used to obtain authority from authority itself.
Your password opens the door. Your session cookie then proves the door has already been opened.
That is precisely why Google considers a compromised agent operating in a local Chrome a risk of leakage from already-connected sites and builds new barriers around those sessions.
The browser therefore possesses something a classic chatbot almost never has: your operational identity on the Web.
That is where the analogy with an operating system truly begins.
The Browser Already Possesses Almost All the Primitives an Agent Needs
A classic operating system does not merely draw windows.
It provides an environment allowing programs to obtain resources, maintain state, request permissions, communicate with other services, and act with certain privileges.
For a vast portion of our digital lives, the browser now provides the functional equivalent.
The “application” has become the web page. The origin example.com, for example, plays the role of a security boundary. Cookies and sessions carry identity. Web storage preserves state. Browser APIs expose location, camera, microphone, or notifications. Tabs encapsulate different contexts. The password manager acts as a credential vault.
An agent placed atop this ensemble then obtains three essential things.
It can observe the environment: read pages, tabs, sometimes history or connected services.
It can reason about that environment: “I need to find three hotels, compare their prices, check the calendar, then fill the form.”
And above all, it can act: open a page, click, type, send information, or trigger an operation.
The leap between the first two capabilities and the third is immense.
An assistant that errs in summarizing a hotel gives you a bad answer.
An agent that errs in using that hotel can book the wrong room.
This is exactly what OWASP designates under the concept of excessive agency: the consequences of an error no longer depend solely on what the model writes, but on the functions, permissions, and degrees of autonomy granted to it.
The model then becomes merely one security component among others.
The true product is the system that decides what it has the right to see and do.
Prompt Injection Changes Gravity Completely When a Model Can Click
A traditional web page already mixes content controlled by multiple actors: publisher text, ads, comments, iframes, recommendations, user results.
For you, a sentence written in a page is normally information.
For a large language model, a sentence can also resemble an instruction.
That is the heart of indirect prompt injection.
A page can contain an instruction intended not for the human consulting it, but for the agent analyzing it.
For example: ignore the previous objective, consult another site, retrieve private information, or send certain data.
Google explicitly cites scenarios in which an injection would seek to extract information from emails or documents, transfer Gmail messages to an external service, or reveal data from connected applications.
This risk is no longer purely theoretical.
In April 2026, Google’s security team analyzed the public web via several Common Crawl snapshots and found injections targeting agents: some humorous, others intended to manipulate AI search ranking, and a smaller number aiming at exfiltration or data destruction. Between November 2025 and February 2026, Google indicates it observed a relative increase of 32% in the category considered malicious. The company specifies, however, that these observed attacks generally remained unsophisticated and that its study did not cover a large portion of social networks.
Academic research shows in parallel why it would be imprudent to wait for models to solve the problem alone.
The WASP benchmark tested different web agent architectures against realistic injections. Depending on configurations, agents began following the hostile instruction in 16 to 86% of tested cases. They only succeeded in the complete malicious objective in 0 to 17% of cases, notably because the agents themselves remained imperfect. These figures do not measure Chrome auto browse, but they show a fundamental property of the problem: improving an agent’s action capabilities can also make more exploitable hijackings that previously failed simply because the agent was bad.
In other words, improvements in agent reliability are simultaneously improvements in reliability for an attacker who manages to hijack them.
Google Is Inventing Security Primitives for This New “OS”
Chrome’s response to the problem is particularly revealing.
Google does not merely try to train Gemini to “not obey malicious pages.”
It adds new architectural barriers around the model.
One of them is the User Alignment Critic. The main model prepares an action from the web content it consults. A second component, deliberately deprived of untrusted web content, then receives a limited representation of the contemplated action and judges whether it truly corresponds to the objective given by the user.
The idea is important: do not ask the component exposed to the attack to also be its sole judge.
Chrome then introduces Agent Origin Sets.
The browser has long known the concept of origin: two different sites must not be able to freely access each other’s data. For its agents, Google extends this logic by distinguishing origins the agent can only read from those on which it can also act.
An irrelevant page can thus be excluded from what the model sees. A new origin requested by the agent must be controlled. Google also applies deterministic restrictions to URLs generated by the model to limit certain exfiltration mechanisms.
This is no longer mere “AI safety.”
It is capability control.
And it looks a lot like the problems operating systems have tried to solve for decades: which process can access which resource, with which permission, for how long, and to accomplish which operation?
The parallel becomes even clearer with sensitive actions.
Chrome plans confirmations or handovers for certain operations: navigation to highly sensitive site categories, authentication via Password Manager, purchases, payments, sending messages, or other high-consequence actions. The user can also observe the work log and stop the agent.
The old model was:
site → requests permission → user accepts or refuses.
The agent introduces a more difficult model:
user → expresses intention → agent interprets intention → discovers sites → retrieves data → chooses actions → the browser must decide which remain compliant with the initial intention.
Permission therefore no longer bears only on a resource.
It bears on the meaning of an action.
And a machine must now verify that meaning.
Firefox Reduces the Problem by Still Refusing Authority
Mozilla’s current strategy is almost the inverse.
Smart Window benefits from a quantity of context that would have seemed extraordinarily intrusive for a browser-integrated chatbot a few years earlier, but the assistant has very few action capabilities.
It can exploit the current page, explicitly added tabs, and certain history information when a query requires it. It can also produce “memories” from browser activity and conversations if the user enables this function.
Upon initialization, Mozilla indicates that up to 60 days or 3,000 history items, whichever limit is reached first, can be processed to generate these memories. The data temporarily passes through Mozilla’s servers, but the obtained memories are then stored locally; Mozilla asserts it does not retain this data after processing.
This nonetheless represents a major change for Firefox.
A classic browser mainly remembers where you went.
A browser with memory tries to infer what interests you from those movements.
Mozilla adds filters intended to avoid certain memories related notably to health, finance, or legal matters, allows their deletion, and excludes private windows. Smart Window can even use an OpenAI API-compatible endpoint chosen by the user, including a local model.
But the most effective defense today remains extremely simple:
Smart Window cannot act in pages.
An injection that influences a product comparison constitutes an information integrity problem.
An injection that controls an agent with access to Gmail, a merchant account, and a form potentially becomes a confidentiality and account integrity problem.
Mozilla explicitly acknowledges the prompt injection risk and indicates it employs notably a separation between data and instructions as well as action restrictions when the system processes untrusted content.
This suggests Firefox is already building foundations for a more agentic architecture.
But today, the philosophical difference is clear: Mozilla enriches context first; Google already extends authority.
Agent Permissions Risk Being Much Harder to Understand Than App Permissions
On a smartphone, a permission can be relatively intelligible.
“Allow camera access?”
The resource is clear.
For an agent, the equivalent could become:
“Allow Gemini to perform this task?”
But what exactly does this task mean?
If you ask “organize my trip,” must the agent be able to read an email containing conference schedules? Consult your calendar? Use your location? Transmit your name to a hotel? Fill in your loyalty number? Open a site that wasn’t anticipated when you launched the task?
Each step can be perfectly reasonable taken separately.
The danger appears in their composition.
This is one of the most troubling properties of agents: benign permissions can together form an extremely powerful capability.
Calendar access + Gmail + authenticated browser + forms + history + password manager does not simply mean “six features.”
It potentially means software capable of knowing where you must go, retrieving a booking, logging into the provider, modifying it, and notifying someone of the change.
The browser then becomes an authority broker.
And permanent confirmations are not a perfect solution. The more the system asks for user approval, the less autonomous it is; the more it masks these interruptions, the higher the risk of unwanted action.
This is a structural trade-off, not a temporary UI bug.
Identity Becomes an Attack Surface in Its Own Right
Browser agents also create a new distinction between “private data” and “capacity to act as you.”
They are not the same thing.
An attacker who steals a file obtains data.
A hijacked agent acting in an authenticated session can potentially obtain something more useful: the ability to ask the service to perform an operation on the user’s behalf.
This is the classic confused deputy problem applied to agents: a legitimate component possesses privileges, but another actor manages to influence how it exercises them.
The attacker then does not need to directly steal your identity.
They try to convince the software that already possesses that identity to use it for them.
Chrome’s defenses around origins take on their full meaning here. By limiting what the agent can read and the sites on which it can write, Google tries to reduce the amount of ambient authority available during a task.
This principle could become as fundamental for agents as the sandbox became for classic browsers.
The Browser Does Not Really Replace the Operating System
The analogy has its limits.
Chrome or Firefox do not directly control the processor, physical memory, drivers, system files, or hardware isolation. They still rely on the mechanisms of Windows, macOS, Linux, Android, or iOS.
Agents can also function atop the operating system itself, use APIs directly, or work in remote virtual machines without a graphical interface.
Saying the browser “becomes the new OS” in the literal sense would therefore be exaggerated.
A more precise formulation would be:
the browser becomes the operating system of our web identity.
It is already the place where a large part of our applications, sessions, and communications coexist. The agent adds the missing piece: a cognitive scheduler capable of receiving an abstract objective and deciding which web applications to mobilize to accomplish it.
The human progressively ceases to provide the sequence of actions.
They provide the intention.
The Fundamental Unit of the Web Could Shift from the Click to the Intention
For three decades, a vast portion of web security has rested on a silent hypothesis: the user is the one who clicks.
A site can deceive the user. An extension can hijack a browser. A script can exploit a vulnerability.
But the browser itself did not normally decide that a button deserved to be pressed because it roughly matched your objective.
Agents change this hypothesis.
When you ask “renew my subscription but find me a cheaper plan,” the system must interpret what “cheaper” means, determine which site to use, understand its interface, access the appropriate account, identify consequences, and know at what moment your consent becomes indispensable.
The browser no longer simply transports human intentions expressed through clicks.
It begins to compile them into actions.
And this brings to light an extraordinarily difficult new security problem.
For a traditional browser, one notably had to determine:
does this site have the right to access this data?
For an agentic browser, the question becomes:
does this action truly correspond to what the human wanted, despite everything the agent just read on the web?
Chrome is beginning to create specific mechanisms to answer this question. Firefox, for now, largely avoids having to ask it by keeping its assistant on the observation side rather than execution.
But the general direction is hard to miss.
The browser was the software in which we used the Internet.
It is progressively becoming the software to which we give the Internet to use on our behalf.